serverless
SAM and Serverless Framework, on the same flat

Having spent a Saturday finding out what SAM hands CloudFormation, the obvious
next question is whether the other tool that writes CloudFormation for you
writes better CloudFormation. So I ported the flat to serverless.yml — five
functions, the device registry, the IoT rule, the schedules, the alarms — and
deployed it beside the real stack under a different stage.
The first thing to say is that this is not a runtime comparison. Both of them
produce a CloudFormation template and hand it to CloudFormation; you can see
Serverless Framework's with serverless package, which leaves it in
.serverless/cloudformation-template-update-stack.json. Same service, same
change sets, same eventual consistency, same three-in-the-morning rollback
behaviour. Everything below is about the authoring layer and the CLI, because
that is all there is to differ about.
One role or five
This is the difference that actually changed my mind about something, so it goes first.
SAM attaches policies per function. The sensor ingest function gets CRUD on one
table and nothing else, because that is where its Policies: block is:
SensorIngestFunction:
  Type: AWS::Serverless::Function
  Properties:
    Policies:
      - DynamoDBCrudPolicy:
          TableName: !Ref DeviceRegistryTable
Serverless Framework, by default, gives the whole service one role:
provider:
  name: aws
  runtime: python3.8
  region: eu-west-1
  iamRoleStatements:
    - Effect: Allow
      Action: [dynamodb:GetItem, dynamodb:PutItem, dynamodb:UpdateItem]
      Resource: !GetAtt DeviceRegistryTable.Arn
    - Effect: Allow
      Action: [iot:Publish]
      Resource: '*'
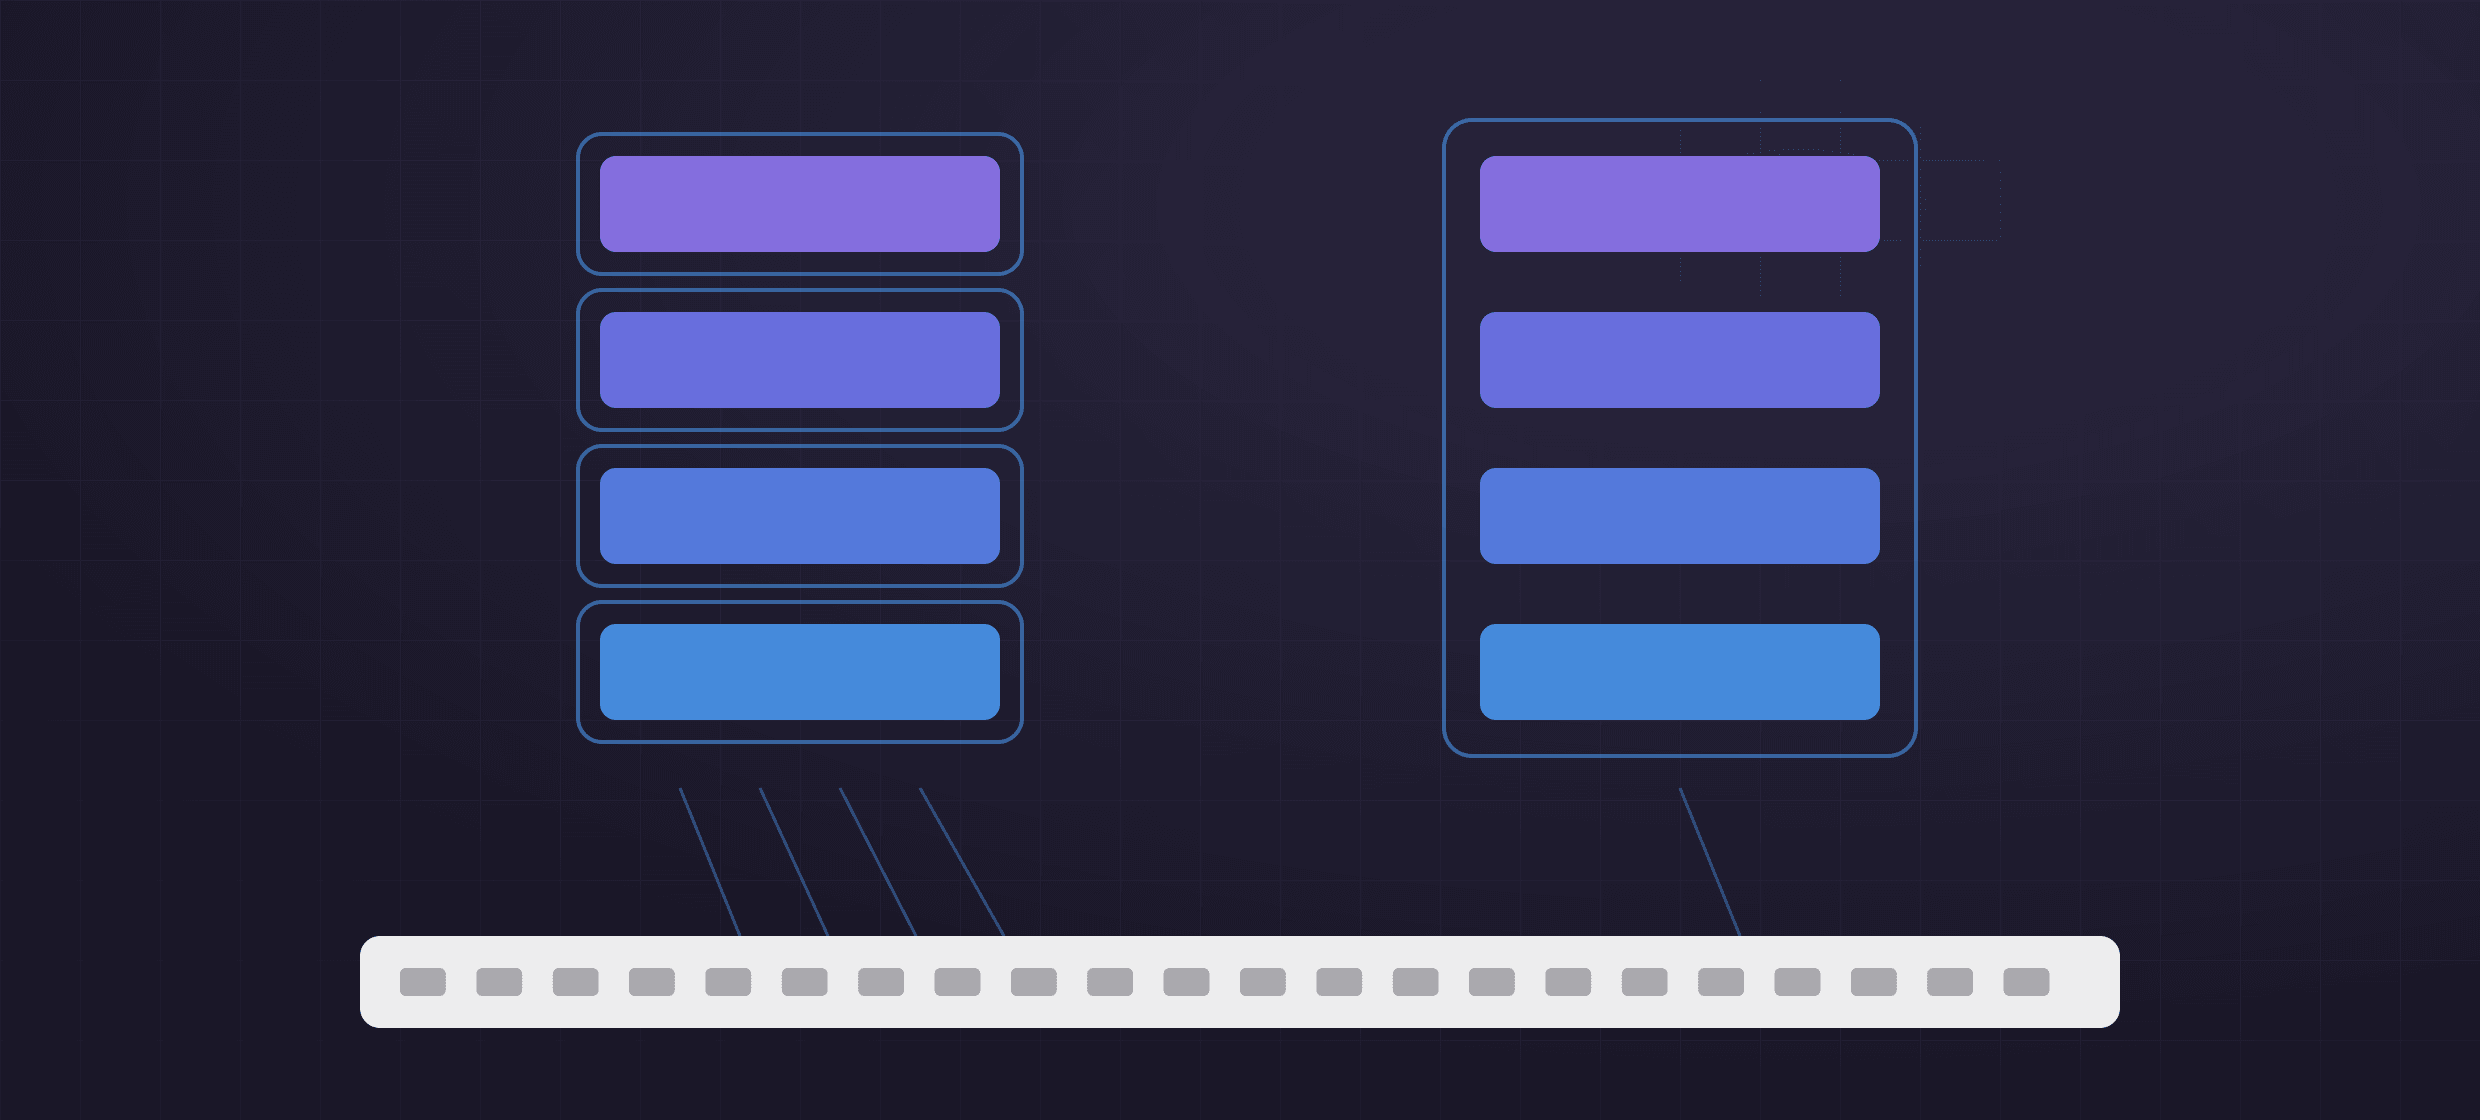
Every function in the service can do everything in that list. The function that reads a temperature can publish to IoT. The function that answers Alexa can write to the table. Nothing in my flat is going to be attacked over this and that is not the point — the point is that the default shape of the file encourages one union of every permission any function needs, and a union only ever grows.
There is a plugin, serverless-iam-roles-per-function, and it works, and the
fact that per-function IAM is a plugin rather than the default tells you what
the tool considers normal. SAM's per-function policies plus the policy template
list is the single strongest thing it has, and this is where I felt it.
Variables, where Serverless Framework is simply better
CloudFormation has parameters, mappings and !Sub. Serverless Framework has a
resolver that reads whatever you point it at:
custom:
  stage: ${opt:stage, self:provider.stage}
  config: ${file(./config/${self:custom.stage}.yml)}

provider:
  environment:
    SKILL_ID: ${ssm:/home-automation/skill-id}
    TABLE: ${self:custom.config.tableName}
The SAM equivalent of that SSM lookup is a template parameter typed
AWS::SSM::Parameter::Value<String> plus a line in samconfig.toml, and the
equivalent of the per-stage config file is a Mappings: block, which is a
lookup table pretending to be a data structure. On this, it is not close.
Serverless Framework treats the deployment as something with inputs. SAM treats
it as a document with parameters, and the difference shows up every single time
you want the dev stack to point somewhere else.
Stages
sls deploy --stage dev does the obvious thing: every resource name carries the
stage, so two stacks coexist without you thinking about it. SAM's answer is a
samconfig.toml with an environment table and --parameter-overrides, and
resource naming you do yourself with !Sub '${AWS::StackName}-...' on every
resource that needs a name.
I only have one stage here, so this cost me nothing and would have cost me a lot at work.
The deploy loop
The thing I did not expect to care about:
sls deploy function -f sensorIngest
That uploads a zip and calls UpdateFunctionCode. It takes about five seconds.
SAM has no equivalent — sam deploy is a change set every time, and for this
stack that is somewhere between forty and ninety seconds depending on what
moved. Over a weekend of fiddling with one handler, the difference is the
difference between staying in the problem and going to make tea.
The counterweight is that sls deploy function deliberately skips
CloudFormation, so the stack and the deployed code drift apart until the next
full deploy. That is fine and it is also exactly the kind of fine that stops
being fine on a team.
SAM's answer to the same problem is sam local invoke against an event file,
which I use constantly and which is genuinely better than the framework's
equivalent for a stack like mine — serverless-offline is built around HTTP
APIs, and there is no HTTP anywhere in this flat.
Plugins are the ecosystem and the bill
Everything Serverless Framework does not do natively, it does with a plugin.
State machines are serverless-step-functions. Vendored Python dependencies
with native extensions are serverless-python-requirements with
dockerizePip: true. Both work well.
Both also mean that a Python project on a machine with no Node.js installed now
has a package.json, a node_modules, and a version matrix between the
framework and each plugin that upgrades independently of it. SAM ships one
binary from AWS and its state machine support is a resource type.
I want to be fair about the direction that cuts: the plugin list is also why Serverless Framework can do things SAM has no story for at all, and if I needed one of those tomorrow I would install it without much soul-searching.
The part that is not technical
Serverless Framework is a product with a company behind it. There is a
dashboard, there are org and app keys in the file, the CLI would like you
to log in, and it phones home unless told not to. None of that is unreasonable
and all of it is a third party standing in the path between my laptop and my
own AWS account, for a stack that turns lamps on.
SAM is a CloudFormation transform and a CLI, both from the vendor whose API I am calling anyway. For this project that asymmetry decides it, and I accept that for a project with a delivery deadline it would decide nothing at all.
Where I landed
The flat stays on SAM. Per-function IAM by default, no second vendor, and the local invoke loop is the one I actually use.
If I were starting something with three stages and four people, I would want
Serverless Framework's variables and its stage handling badly enough to take
the plugin sprawl, and I would install serverless-iam-roles-per-function on
day one before anyone had the chance to grow the shared role.
What nags at me after two weekends is that both files are YAML with a preprocessor in front. Every argument above is about whose preprocessor is better, and none of it is about the thing I keep wanting, which is a loop. Four schedules are four near-identical blocks in both tools. That is a different post, and I think I am going to have to write the stack a third time to have it.

Written by
Deyan Peev
Founding Engineer · Sofia, Bulgaria



